What If the Smartest Part of an AI Coach Never Spoke?
We have early access to TypeSafe's new Jev model. It doesn't chat, write training plans or explain itself, which is exactly why I think it could be interesting for Primed.
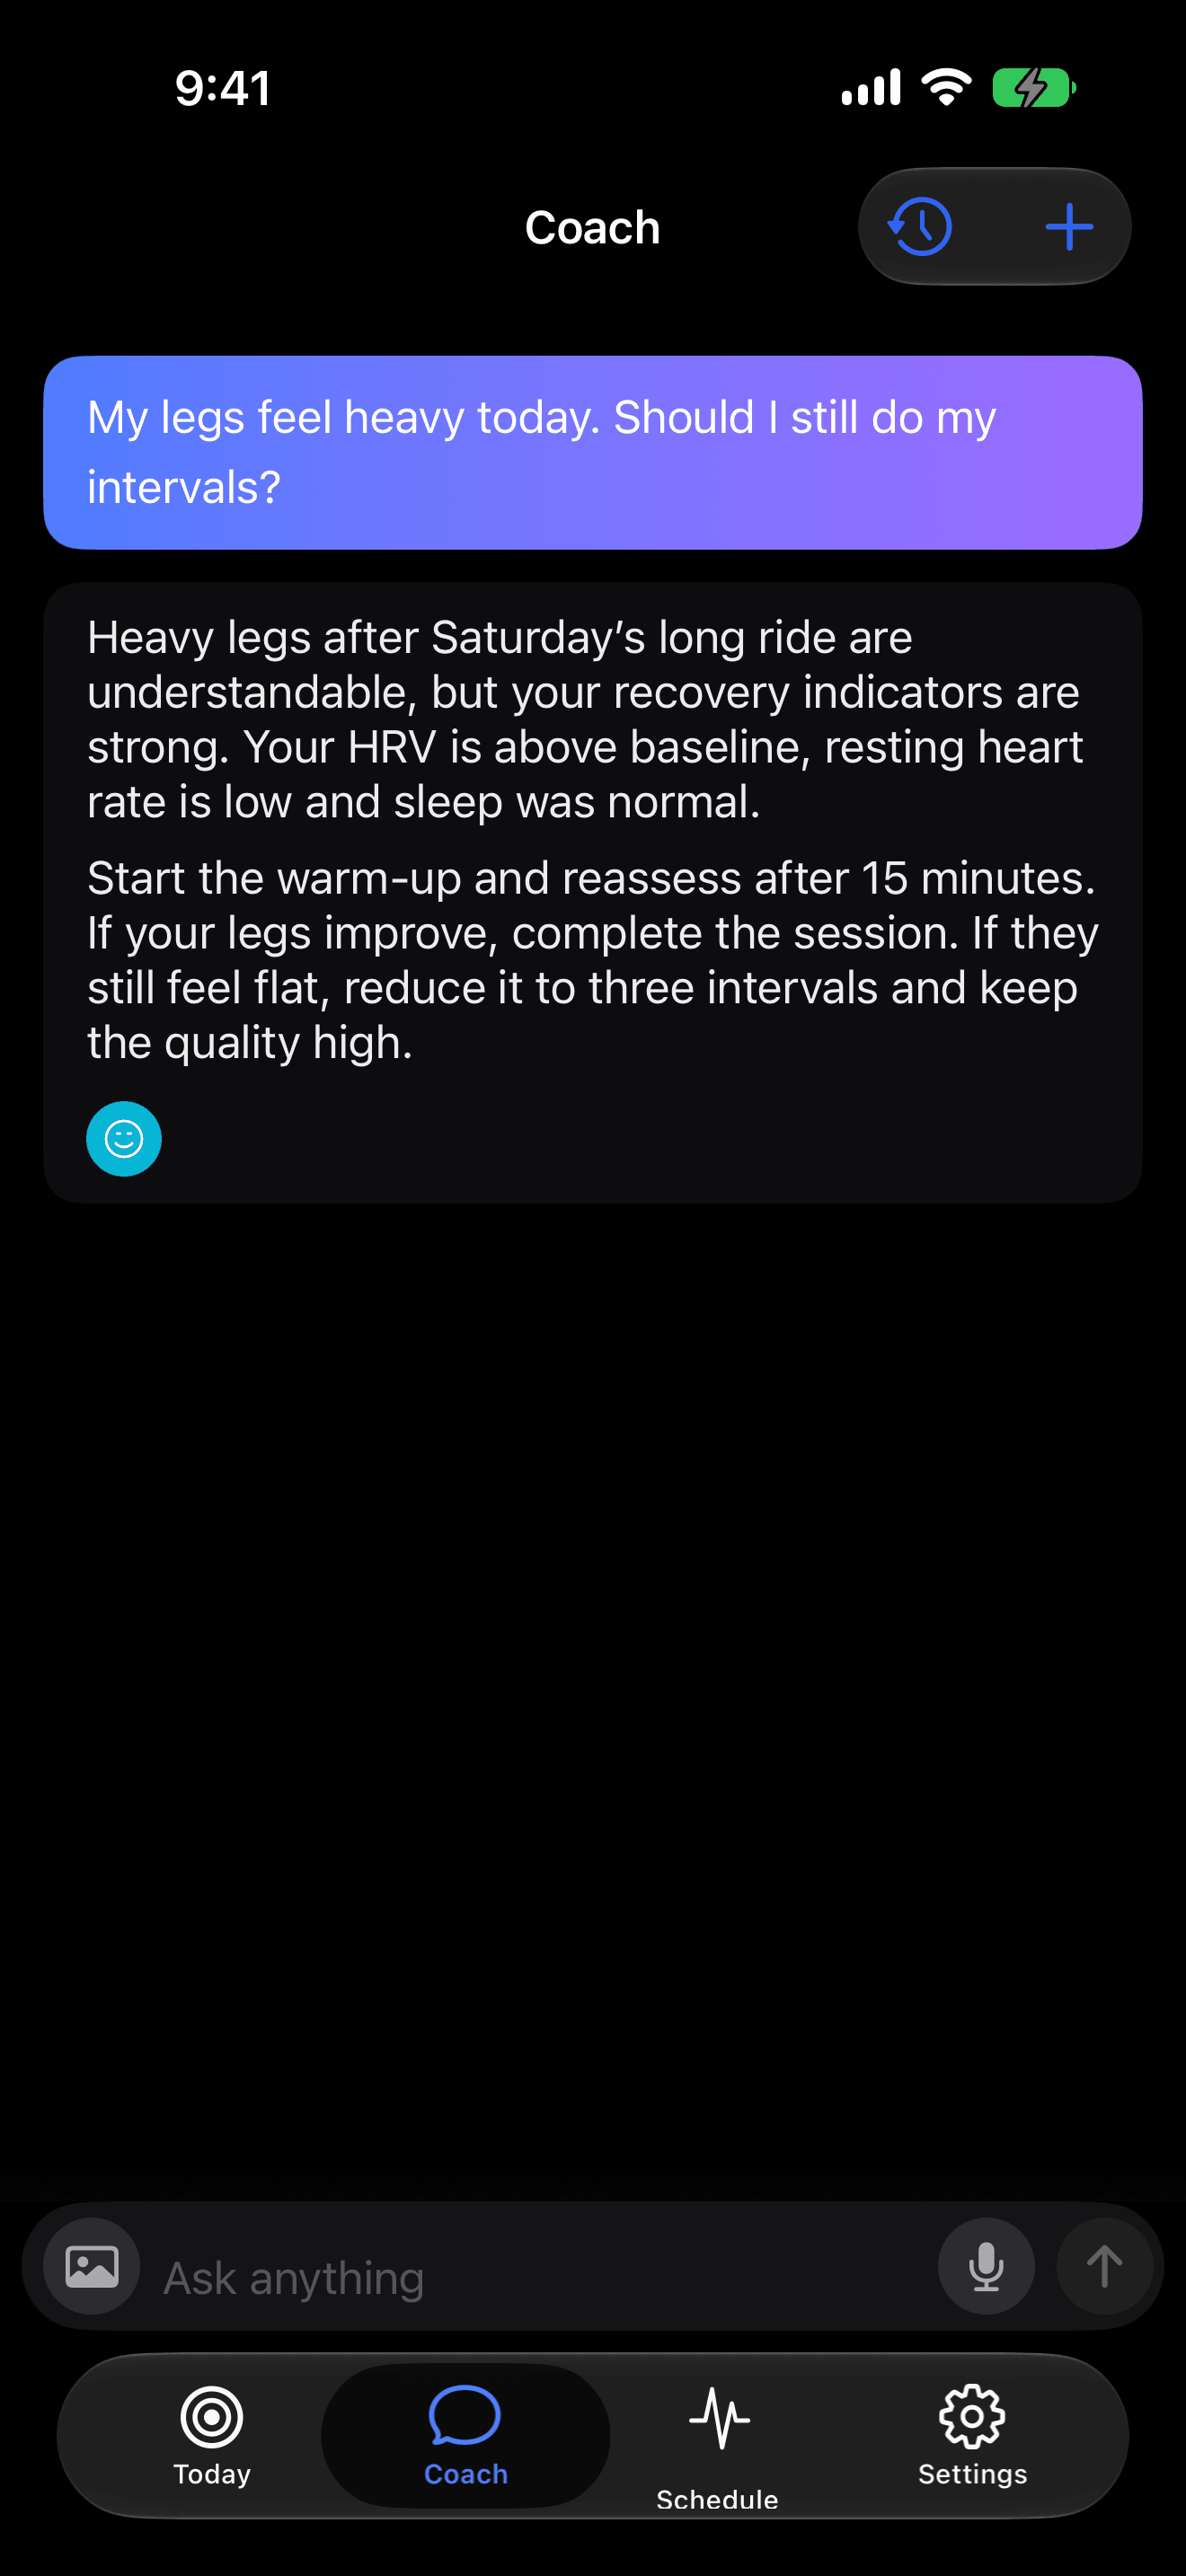
For most of the recent AI boom, we have tended to treat intelligence and language as if they are the same thing. We give a large language model some context, ask it to reason about a problem, let it make a decision, and then have it explain that decision back to us in words.
That approach has been central to how we built Primed. Primed was designed around an LLM-first architecture, so the language model is not just sitting on top of the product as a chatbot. It is involved in how the system works. It can interpret what an athlete is asking, look at the right context, select tools, analyse training history and help decide what should happen next.
Over time, though, we have become much more interested in the context surrounding the model. A lot of the hard work is not simply choosing the most capable model. It is deciding what information the model should see, how much of it should be included, what should be remembered, and what can safely be ignored.
Now we want to test another question.
Does every intelligent decision inside an AI system actually need a language model?
Key takeaways
- Not every intelligent decision in an AI system requires a language model.
- Decision models evaluate structured state, returning deterministic classifications and probabilities.
- Primed is testing Jev for data conflict, intent detection, and safety verification.
- The future is specialized models and deterministic code collaborating together.
A model that isn't trying to talk to you
TypeSafe recently gave us early access to Jev, the first model in its System One family. It is a very different proposition from models such as GPT, Claude or Gemini because it is not designed to generate prose.
Instead, you give it some structured state and ask it tightly defined questions. It can choose between predefined options, score something against a rubric, or estimate the probability that a statement is true. What comes back is structured data that software can use directly.
That makes the mental model quite different from the way we usually think about AI.
Instead of asking a language model, "Look at everything we know about this athlete and decide whether today's session should change", we could break the problem into smaller judgments. Is the recovery data reliable enough to act on? Is there meaningful evidence of abnormal fatigue? Does the athlete's subjective feedback conflict with their wearable data? Is there enough evidence here to justify changing the planned session?
Those are still intelligent questions, but they do not necessarily require a conversational answer.
That is the part I find interesting. The AI can make a judgment, while the software remains in control of what happens next.
Why this fits an endurance coach surprisingly well
An endurance coach actually makes a huge number of small judgments before arriving at a recommendation. Some of those judgments are completely deterministic and should stay that way.
If we want to know an athlete's seven-day load, how much their power has dropped, or how long it has been since their last hard session, normal software should calculate that. There is no reason to ask a model to perform arithmetic that code can do exactly.
There is another category of problem, though, that sits between calculation and conversation. This is where things get more interesting.
Is this sleep reading plausible, or does it look wrong? Is this workout meaningfully harder than the athlete expected? Does a message mean the athlete wants their plan changed, or are they simply asking why the workout exists? Is something worth remembering for months, or is it just temporary context from today? Is the evidence strong enough to alter training, or should the system wait for more information?
These are not really maths problems, and they are not necessarily writing problems either. They are judgments.
That may be exactly the kind of work a model like Jev is better suited to.
A different way to split the work
One of the things we want to explore is whether Primed should separate different kinds of intelligence more explicitly.
Code would continue to compute facts such as power, heart rate, training load, dates, durations and trends. Those things are deterministic and should remain deterministic.
A decision model like Jev could then evaluate narrower questions around classification, ambiguity, relevance, confidence or risk. A frontier language model would still handle the areas where broader reasoning, synthesis, language and explanation are important.
Primed itself would remain responsible for controlling the action. The application decides what is allowed to happen automatically, what requires more information and what should be escalated or blocked.
If that works well, the architecture starts to look quite different from simply putting one very capable LLM in the middle of everything.
Instead, you have different parts of the system doing the jobs they are best at.
So we're going to test it on real Primed problems
The plan is not to build artificial demos that make Jev look good. We want to put it against the kinds of problems we actually encounter when building an adaptive endurance coach.
One obvious area is conflicting athlete data. Modern endurance athletes can generate an extraordinary amount of telemetry, and the problem is not always getting more data. Sometimes the problem is deciding what to trust.
Wearables can disagree. Measurements can be missing. A device can record something that is technically valid but clearly looks wrong in context.
We want to see whether a decision model can reliably distinguish between data that looks normal, data that appears anomalous, situations where multiple signals conflict, and cases where there simply is not enough evidence to make a training adjustment.
The confidence is just as interesting as the answer. If the evidence becomes ambiguous, does the model become less certain, or does it continue producing confident decisions anyway?
That is something we can test.
Should we change today's training?
Another obvious Primed problem is training adaptation.
A surprisingly large part of adaptive coaching comes back to a very simple question: should we change the plan?
The actual answer can depend on a lot of things, including recent workload, workout completion, sleep, subjective feedback, illness, soreness, recovery trends and the importance of the next planned session.
Some of those inputs are numerical and should be handled in code. What we want to test is whether Jev can help with the semantic judgment around whether the evidence is significant enough to justify a change.
That is quite different from asking it to build a training plan.
It is a smaller and more focused problem, which is probably where this type of model makes the most sense.
Understanding what the athlete actually means
Intent detection is another area we want to look at.
If an athlete says, "That was much harder than I expected", there are several things Primed could potentially do. It could record the feedback, inspect recent recovery data, look at upcoming training, ask a follow-up question, or simply acknowledge what the athlete said.
A frontier LLM can obviously make that decision, but it may be overkill to use a large generative model every time Primed needs to decide which path to take.
If a smaller decision model can reliably handle that first routing step, then the more capable language model can be reserved for the situations where its broader reasoning and language abilities are actually useful.
That could have implications for speed, cost and, potentially, consistency.
What should an AI coach remember?
Persistent memory is another area where this could become useful.
Long-term AI systems need to decide what deserves to be remembered and what does not. "I prefer training before work" could remain relevant for years. "I slept terribly last night" is probably useful today and then becomes stale very quickly. "I'm travelling every second week for the next three months" belongs somewhere in between.
We already think of memory as an engineering problem rather than simply saving every conversation forever.
A decision model could potentially become one part of that process by classifying information as a durable preference, temporary constraint, short-lived observation or irrelevant detail.
Again, the interesting part is that this does not require beautifully generated language. It just requires a good decision.
Using AI to check AI
There is another possibility that I think may turn out to be even more interesting.
Jev may not only be useful before a language model is called. It could also be used after one.
Imagine Primed's coaching model proposes a training adjustment. A separate decision model could then evaluate a few narrow questions before the change is accepted. Is the recommendation supported by the supplied athlete state? Does it conflict with an explicit constraint? Is the adjustment unusually aggressive? Is there enough evidence to act, or should the system ask for more information first?
That starts to look less like one large AI brain and more like a collection of specialised forms of intelligence checking one another.
For autonomous AI systems, I suspect that kind of architecture is going to become increasingly important.
The weaknesses are part of the experiment
One reason I like this experiment is that TypeSafe is quite explicit about what Jev is not designed to do.
The current model is not intended for precise arithmetic. It is not a good place to calculate dates. It can be overly literal, performance can fall away when too much irrelevant context is included, and complex chains of indirect reasoning are not really its target.
That does not make the model less interesting. In some ways it makes the experiment better, because it forces us to be more disciplined about where a model should and should not be used.
If code can calculate something exactly, code should calculate it. If the system already knows that two sessions are 48 hours apart, there is no reason to ask an AI model to work that out again.
The useful part of the model is the judgment.
The question is whether we can define that boundary well enough.
We want to measure it properly
We do not want to come away from this experiment saying it works because we found three impressive examples.
We plan to build a private evaluation set based on situations that Primed actually encounters. That will include straightforward cases, ambiguous cases, conflicting signals and awkward edge cases designed to expose where the model falls over.
We can then compare Jev with the approaches we already use.
Correctness obviously matters, but we also want to look at consistency across similar inputs, behaviour when information is incomplete, sensitivity to irrelevant context, calibration of uncertainty, latency, cost and stability across repeated runs.
We also want to perturb the scenarios. If one genuinely important fact changes, does the answer change with it? If we add irrelevant information, does the model stay focused? If a situation becomes genuinely ambiguous, does confidence drop?
Those behaviours are probably more important to us than whether a model looks impressive in a demo.
What about the speed and cost claims?
TypeSafe is making some very large performance claims around Jev and its System One approach, particularly around latency and cost compared with conventional LLM workflows.
Those numbers are interesting, but I do not want to assume they will automatically transfer to Primed.
Different workloads behave differently, and endurance coaching is not what Jev was specifically built to demonstrate.
That is why having early access is useful. We can try it against a real system, with real architectural constraints, and see where it genuinely helps.
If it turns out to be dramatically faster and just as reliable, that is obviously interesting. If it is only somewhat faster but far more predictable, that could still be valuable. If it is extremely fast but poor at the judgments we care about, then it is not useful to us.
The confidence estimates may turn out to matter just as much as the raw answer. A system that knows when it is uncertain is often more useful than one that is slightly more accurate but confidently wrong.
Maybe LLM-first was only the beginning
When we first described Primed as LLM-first, the main idea was that AI should not simply be bolted onto a conventional application as a chat window.
I still believe that.
But the architecture of AI software is changing very quickly, and I am increasingly interested in the idea that the future is not one enormous model responsible for every intelligent operation inside a product.
It may be a combination of deterministic software and several different types of models, each doing the thing it is best suited to do.
One model may decide. Another may reason. Another may verify. Traditional software may calculate the facts and enforce the boundaries between them.
The athlete does not need to know any of that is happening. From their point of view, it should still feel like one coherent coach.
That is what we are going to explore with Jev.
It may turn out that one of the most useful AI models inside Primed is the one the athlete never actually talks to.